

SECTION 1
Historical Context & Motivation
Long before modern statistics existed as a formal discipline, scholars struggled with a deceptively simple question: how do you describe things that differ from one another? Early census-takers in ancient Egypt and Rome recorded attributes of their populations — age, occupation, land holdings — without any standardized language for distinguishing between types of information. The lack of a precise vocabulary for variables meant that numerical counts were often conflated with categorical labels, leading to confusion in record-keeping and analysis. The evolution of a rigorous classification system for variables is, in many ways, the story of statistics itself — a discipline that gained power precisely when it learned to speak clearly about the nature of variation.
1662 • Graunt's Bills of Mortality
1749 • Achenwall Coins 'Statistik'
1900 • Pearson's Chi-Square Test
1946 • Stevens' Scales of Measurement
2000s • Big Data & Variable Taxonomy
This historical arc reveals a consistent theme: every major advance in statistics — from Graunt's demographic tables to modern machine-learning pipelines — has depended on correctly identifying what kind of variable you are working with. The AP Statistics curriculum opens with this topic precisely because every subsequent technique — from constructing a histogram to running a two-sample t-test — requires you to first answer the question: What type of data do I have?
SECTION 2
Core Principles & Definitions
At its core, a variable is any characteristic that can differ from one individual (or observational unit) to another. The word 'variable' itself comes from the Latin variabilis, meaning 'changeable.' In statistics, we study variables because understanding how and why they vary is the central pursuit of the discipline. An individual (also called a case or observational unit) is the entity about which data are collected — a person, a city, a biological specimen, a manufactured part. Every row in a well-organized data table represents one individual, and every column represents one variable.
Categorical (Qualitative) Variables
Quantitative (Numerical) Variables
Discrete Quantitative Variables
Continuous Quantitative Variables
Individuals / Observational Units
KEY TAKEAWAY
SECTION 3
Visual Explanation: The Variable Taxonomy
The diagram above captures the essential decision process you should follow every time you encounter a new dataset. Begin at the top: you have a variable. Ask yourself, Does this variable record a group membership, or does it record a numerical quantity for which arithmetic is meaningful? If the values are labels — even if those labels happen to be numbers (like jersey numbers or social security digits) — the variable is categorical. If the values represent quantities where computing a difference or average makes sense, the variable is quantitative. From there, further sub-classification refines your choice of display and summary statistics.
SECTION 4
How Variable Type Determines Analysis
While the concept of variables may seem purely definitional, the classification carries deep analytical consequences. The type of variable dictates which graphs, numerical summaries, and inference procedures are appropriate. Misidentifying a variable type is one of the most common — and most consequential — errors in introductory statistics, because it cascades through every subsequent step.
Matching Variable Type to Statistical Tools
| Variable Type | Appropriate Graphs | Appropriate Summaries | Common Inference |
|---|---|---|---|
| Categorical | Bar chart, pie chart, mosaic plot | Counts, proportions, mode | Chi-square test, z-test for proportions |
| Quantitative (Discrete) | Dotplot, histogram, stemplot | Mean, median, std. dev., IQR | t-tests, regression (when appropriate) |
| Quantitative (Continuous) | Histogram, boxplot, normal probability plot | Mean, median, std. dev., IQR, range | t-tests, confidence intervals for means, regression |
How variable classification maps to the statistical toolkit.
Notice a critical pattern: you would never compute a mean for a categorical variable, because the labels carry no inherent numerical magnitude. Averaging the category codes 1 = Democrat, 2 = Republican, 3 = Independent yields 2.0, which does not mean 'Republican.' Similarly, you would not create a histogram of blood types, because histograms require a number line on which to place values. The golden rule is: identify the variable type before selecting any statistical tool.
AP EXAM TIP
SECTION 5
Detailed Classification: Levels of Measurement
While the AP Statistics exam focuses primarily on the categorical-versus-quantitative distinction, it is valuable to understand Stevens' levels of measurement because they add nuance to why certain operations are permissible with some data and not others. The four levels — nominal, ordinal, interval, and ratio — form a hierarchy in which each successive level preserves all the properties of the one below it and adds a new one.
For AP Statistics purposes, the practical mapping is straightforward: nominal and ordinal data are treated as categorical, while interval and ratio data are treated as quantitative. The ordinal level sits at a sometimes-ambiguous boundary: a 5-point Likert scale ('strongly disagree' to 'strongly agree') is technically ordinal, but researchers often treat it as approximately quantitative for convenience. Being aware of this tension will help you critically evaluate real-world studies.
NUMERICAL CODES ≠ QUANTITATIVE
SECTION 6
Worked Example: Classifying Variables in a Dataset
Suppose a university registrar collects the following information for each student: (1) student ID number, (2) major, (3) GPA, (4) number of credits completed, (5) class standing (freshman, sophomore, junior, senior), and (6) whether the student lives on campus (yes/no). Let us classify each variable and justify our reasoning step by step.
Classifying Six Variables in a University Dataset
- 1
Step 1 — Student ID Number
Although student ID numbers are numerical (e.g., 10482937), they serve only as unique identifiers. You would never compute an average student ID. The arithmetic operations of addition and subtraction yield no meaningful result.Categorical (nominal) - 2
Step 2 — Major
Major is a label that places each student into a group — Biology, History, Computer Science, etc. There is no inherent numerical order among these categories.Categorical (nominal) - 3
Step 3 — GPA
GPA ranges from 0.00 to 4.00 and represents a numerical summary of academic performance. Computing the mean GPA of a group of students is meaningful: the difference between a 3.5 and a 3.0 is the same as between a 2.5 and a 2.0 on the GPA scale. GPA can take many possible values within its range (e.g., 3.47, 2.81), so it behaves as continuous, though it is often rounded.Quantitative (continuous) - 4
Step 4 — Number of Credits Completed
Credits are counted in whole units — 30, 64, 97, etc. Arithmetic is meaningful (a student with 90 credits has completed 30 more than a student with 60). Because the values are counts restricted to non-negative integers, this is discrete.Quantitative (discrete) - 5
Step 5 — Class Standing
Freshman, sophomore, junior, and senior are ordered categories — there is a natural progression. However, the 'distance' between freshman and sophomore is not quantifiable in the same way a distance in credits would be. This is ordinal. On the AP exam, it would be classified as categorical.Categorical (ordinal) - 6
Step 6 — On-Campus Residence (Yes/No)
This is a dichotomous (two-level) label. Each student is placed in one of two groups. There is no order and no numerical magnitude. This is a straightforward categorical variable.Categorical (nominal)
THE ONE-QUESTION TEST
SECTION 7
Strengths & Limitations of Variable Classification
The categorical-versus-quantitative framework is powerful, but like any classification system, it has both strengths and limitations. Understanding these will help you think more flexibly when you encounter ambiguous cases on the AP exam and in real research.
| Strengths | Limitations |
|---|---|
| Provides a clear decision rule for choosing graphs and summaries, reducing analytical errors. | Some variables sit at the boundary: ordinal data with many levels (e.g., a 1–100 pain scale) may be treated as quantitative in practice. |
| Universally accepted taxonomy in introductory statistics — ensures consistent communication among researchers. | Binary categorical variables (yes/no) can be numerically coded as 0/1 and legitimately used in regression, blurring the line. |
| Forces analysts to think carefully before applying arithmetic operations, preventing meaningless calculations. | Does not easily accommodate modern data types (text, images, geospatial data) without extension. |
| Simple enough for introductory courses while being foundational for advanced methods. | Students sometimes over-rely on whether values 'look like numbers' rather than asking whether arithmetic is meaningful. |
Strengths and limitations of the standard variable classification framework.
CONTEXT IS KING
SECTION 8
Connection to Advanced Theory & Later Units
The variable taxonomy you learn in Unit 1 is not merely an academic exercise — it is the scaffolding for the entire AP Statistics course. Every later unit builds upon your ability to correctly identify variable types, and the sophistication of the analysis you can perform grows as you combine different variable types together.
| Later AP Topic | Variable Types Involved | Why Classification Matters |
|---|---|---|
| One-variable displays (Unit 1–2) | One categorical OR one quantitative | Determines whether you use a bar chart or histogram; whether you report proportions or mean/SD. |
| Two-variable displays (Unit 2) | Two categorical, two quantitative, or one of each | Cat. × Cat. → two-way table; Quant. × Quant. → scatterplot; Cat. × Quant. → side-by-side boxplots. |
| Linear regression (Unit 2–3) | Two quantitative (explanatory and response) | Regression requires both variables to be quantitative; the roles (explanatory vs. response) add further structure. |
| Inference for proportions (Unit 6–8) | One or two categorical | z-tests and confidence intervals for proportions apply only to categorical success/failure data. |
| Inference for means (Unit 6–8) | One or two quantitative | t-tests and t-intervals require quantitative data; applying them to categorical data produces nonsense. |
How the variable taxonomy connects to later AP Statistics units.
Beyond AP Statistics, the variable classification framework extends into multivariate analysis, where you might encounter dummy variables (categorical variables encoded as 0/1 for use in regression) and mixed-type datasets that require both numerical and categorical methods simultaneously. In machine learning, the distinction between feature types — numeric versus categorical — is one of the first decisions in any preprocessing pipeline, determining how data are encoded, scaled, and fed into models. Mastering the language of variables now gives you fluency in a vocabulary that serves across all quantitative disciplines.
SECTION 9
Practice Problems
Question 1: CONCEPTUAL
- A. Quantitative and discrete, because phone numbers are whole numbers.
- B. Quantitative and continuous, because phone numbers can take many different values.
- C. Categorical and nominal, because phone numbers serve as identifiers and arithmetic operations on them are meaningless.
- D. Categorical and ordinal, because phone numbers can be arranged in numerical order.
- E. It depends on whether the phone numbers contain area codes.
Show answer (C)
Question 2: BASIC CALCULATION
- A. The average student is between a sophomore and a junior.
- B. The mean is not a meaningful summary because class year is a categorical (ordinal) variable.
- C. Most students are sophomores.
- D. The data are skewed to the right because 2.4 is below the midpoint of the scale.
- E. The mean is valid and indicates the typical student has completed 2.4 years of college.
Show answer (B)
Question 3: INTERMEDIATE
- A. 2
- B. 3
- C. 4
- D. 5
- E. 1
Show answer (B)
Question 4: APPLIED
4 ptsShow answer
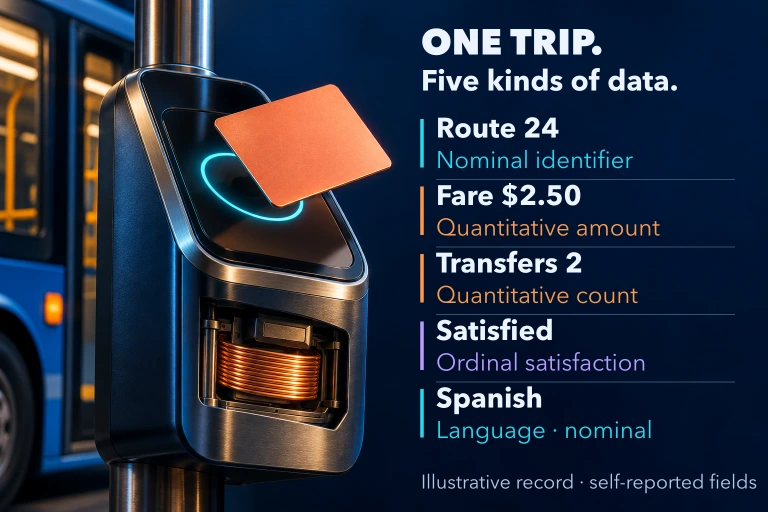
Question 5: CRITICAL THINKING
4 ptsShow answer
SUMMARY
Lesson Summary
Summary
A variable is any characteristic that varies across individuals (observational units) in a dataset. Variables are classified as categorical (qualitative) when they place individuals into groups or categories, and as quantitative (numerical) when they take on values for which arithmetic operations are meaningful. Categorical variables subdivide into nominal (no order) and ordinal (ordered categories), while quantitative variables subdivide into discrete (countable) and continuous (measurable on a continuum).
This classification matters because it determines the entire downstream analysis: categorical variables are summarized with counts, proportions, and bar charts, while quantitative variables are summarized with means, medians, standard deviations, and histograms or boxplots. A critical AP exam skill is recognizing that numbers do not automatically make a variable quantitative — zip codes, ID numbers, and numerical codes for categories are all categorical. Always ask: Does computing the mean of this variable produce a meaningful result? The answer to that question is your guide to correct variable classification and, consequently, to valid statistical analysis.